Minglai Yang
I build language models that humans can understand, and trust. 

📧 minglai.yang@scale.com
📍 San Francisco, CA, USA
I am a Research Scientist at  Scale AI, where I work on agents and RL environments (AgentEnv, Scale’s open-source RL environment framework). Most recently, I studied how language models develop in-context learning and introduced Rubric Dropout, a simple way to mitigate reward hacking in rubric-as-reward RL. Earlier in 2026, I was a Senior Member of Technical Staff at
 Abaka AI. I received my B.S. in
 Computer Science from the University of Arizona (
GPA: 4.0/4.0) in Fall 2025, graduating summa cum laude in just over 2 years and receiving the Best Senior Award.
My research focuses on building LLMs that are trustworthy: robust (EMNLP 25), explainable (TMLR 26) and useful (EMNLP 25). Ultimately, I’m interested in these two overarching questions:
- 🔍 Deconstruction of LLMs: How can we open the black box to reveal the internal mechanisms?
- 🛠️ Reconstruction toward Trustworthy LLMs: How do we translate mechanistic insight into models that are robust, explainable, and useful in practice?
During my undergraduate years, I was fortunate to conduct research co-advised by Profs. Mihai Surdeanu, Liangming Pan, Kobus Barnard and Steven Bethard, in  CLULAB,
 IVILAB and
 ML4AI LAB. I also collaborated with Profs. Adarsh Pyarelal, William Yang Wang and Chicheng Zhang. As Founder & President of
 AI Club at UA, I ran workshops, hosted invited speakers, and led industry collaborations—raising $14K+ to support student AI research and education.
In summer 2025, I was a research intern at  Knowledge Engineering Group (KEG), Tsinghua University, supervised by Prof. Juanzi Li, working on LLM reasoning mechanisms. Before that, I worked as a Machine Learning Engineer intern at
 CoreTechs.
news
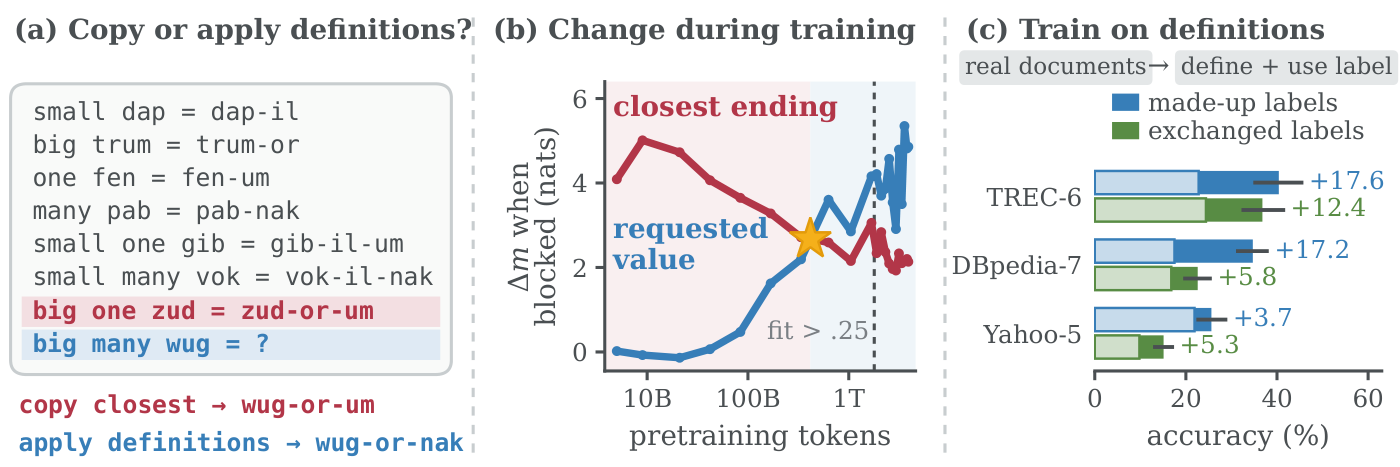
| Oct 13, 2026 | New paper from my work at Scale AI: From Copying to Composition — a controlled study of how language models develop in-context learning, separating copying a nearby demonstration from composing information across the prompt. 🧩 |
|---|---|
| Aug 27, 2026 | Dr. DocBench is featured as an official challenge track at DocInsights 2026, the Workshop on Document Intelligence and Understanding at EMNLP 2026 (Budapest) 🎉 The expert-level document parsing challenge is live on EvalAI through October 10, 2026. |
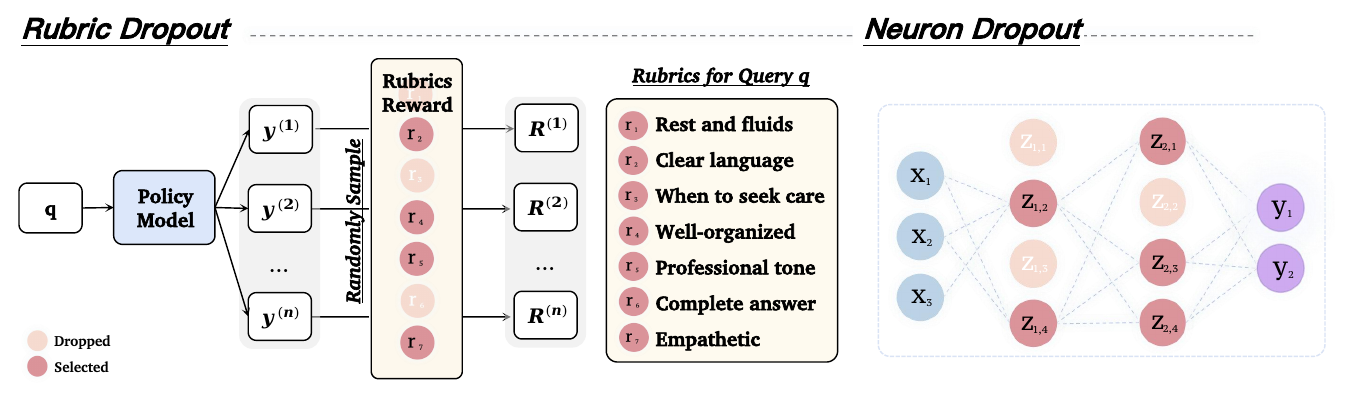
| Aug 12, 2026 | New paper from my work at Scale AI: Rubric Dropout — a one-line fix that mitigates reward hacking in rubric-as-reward RL by randomly dropping rubric criteria at every training step. 🎲 |
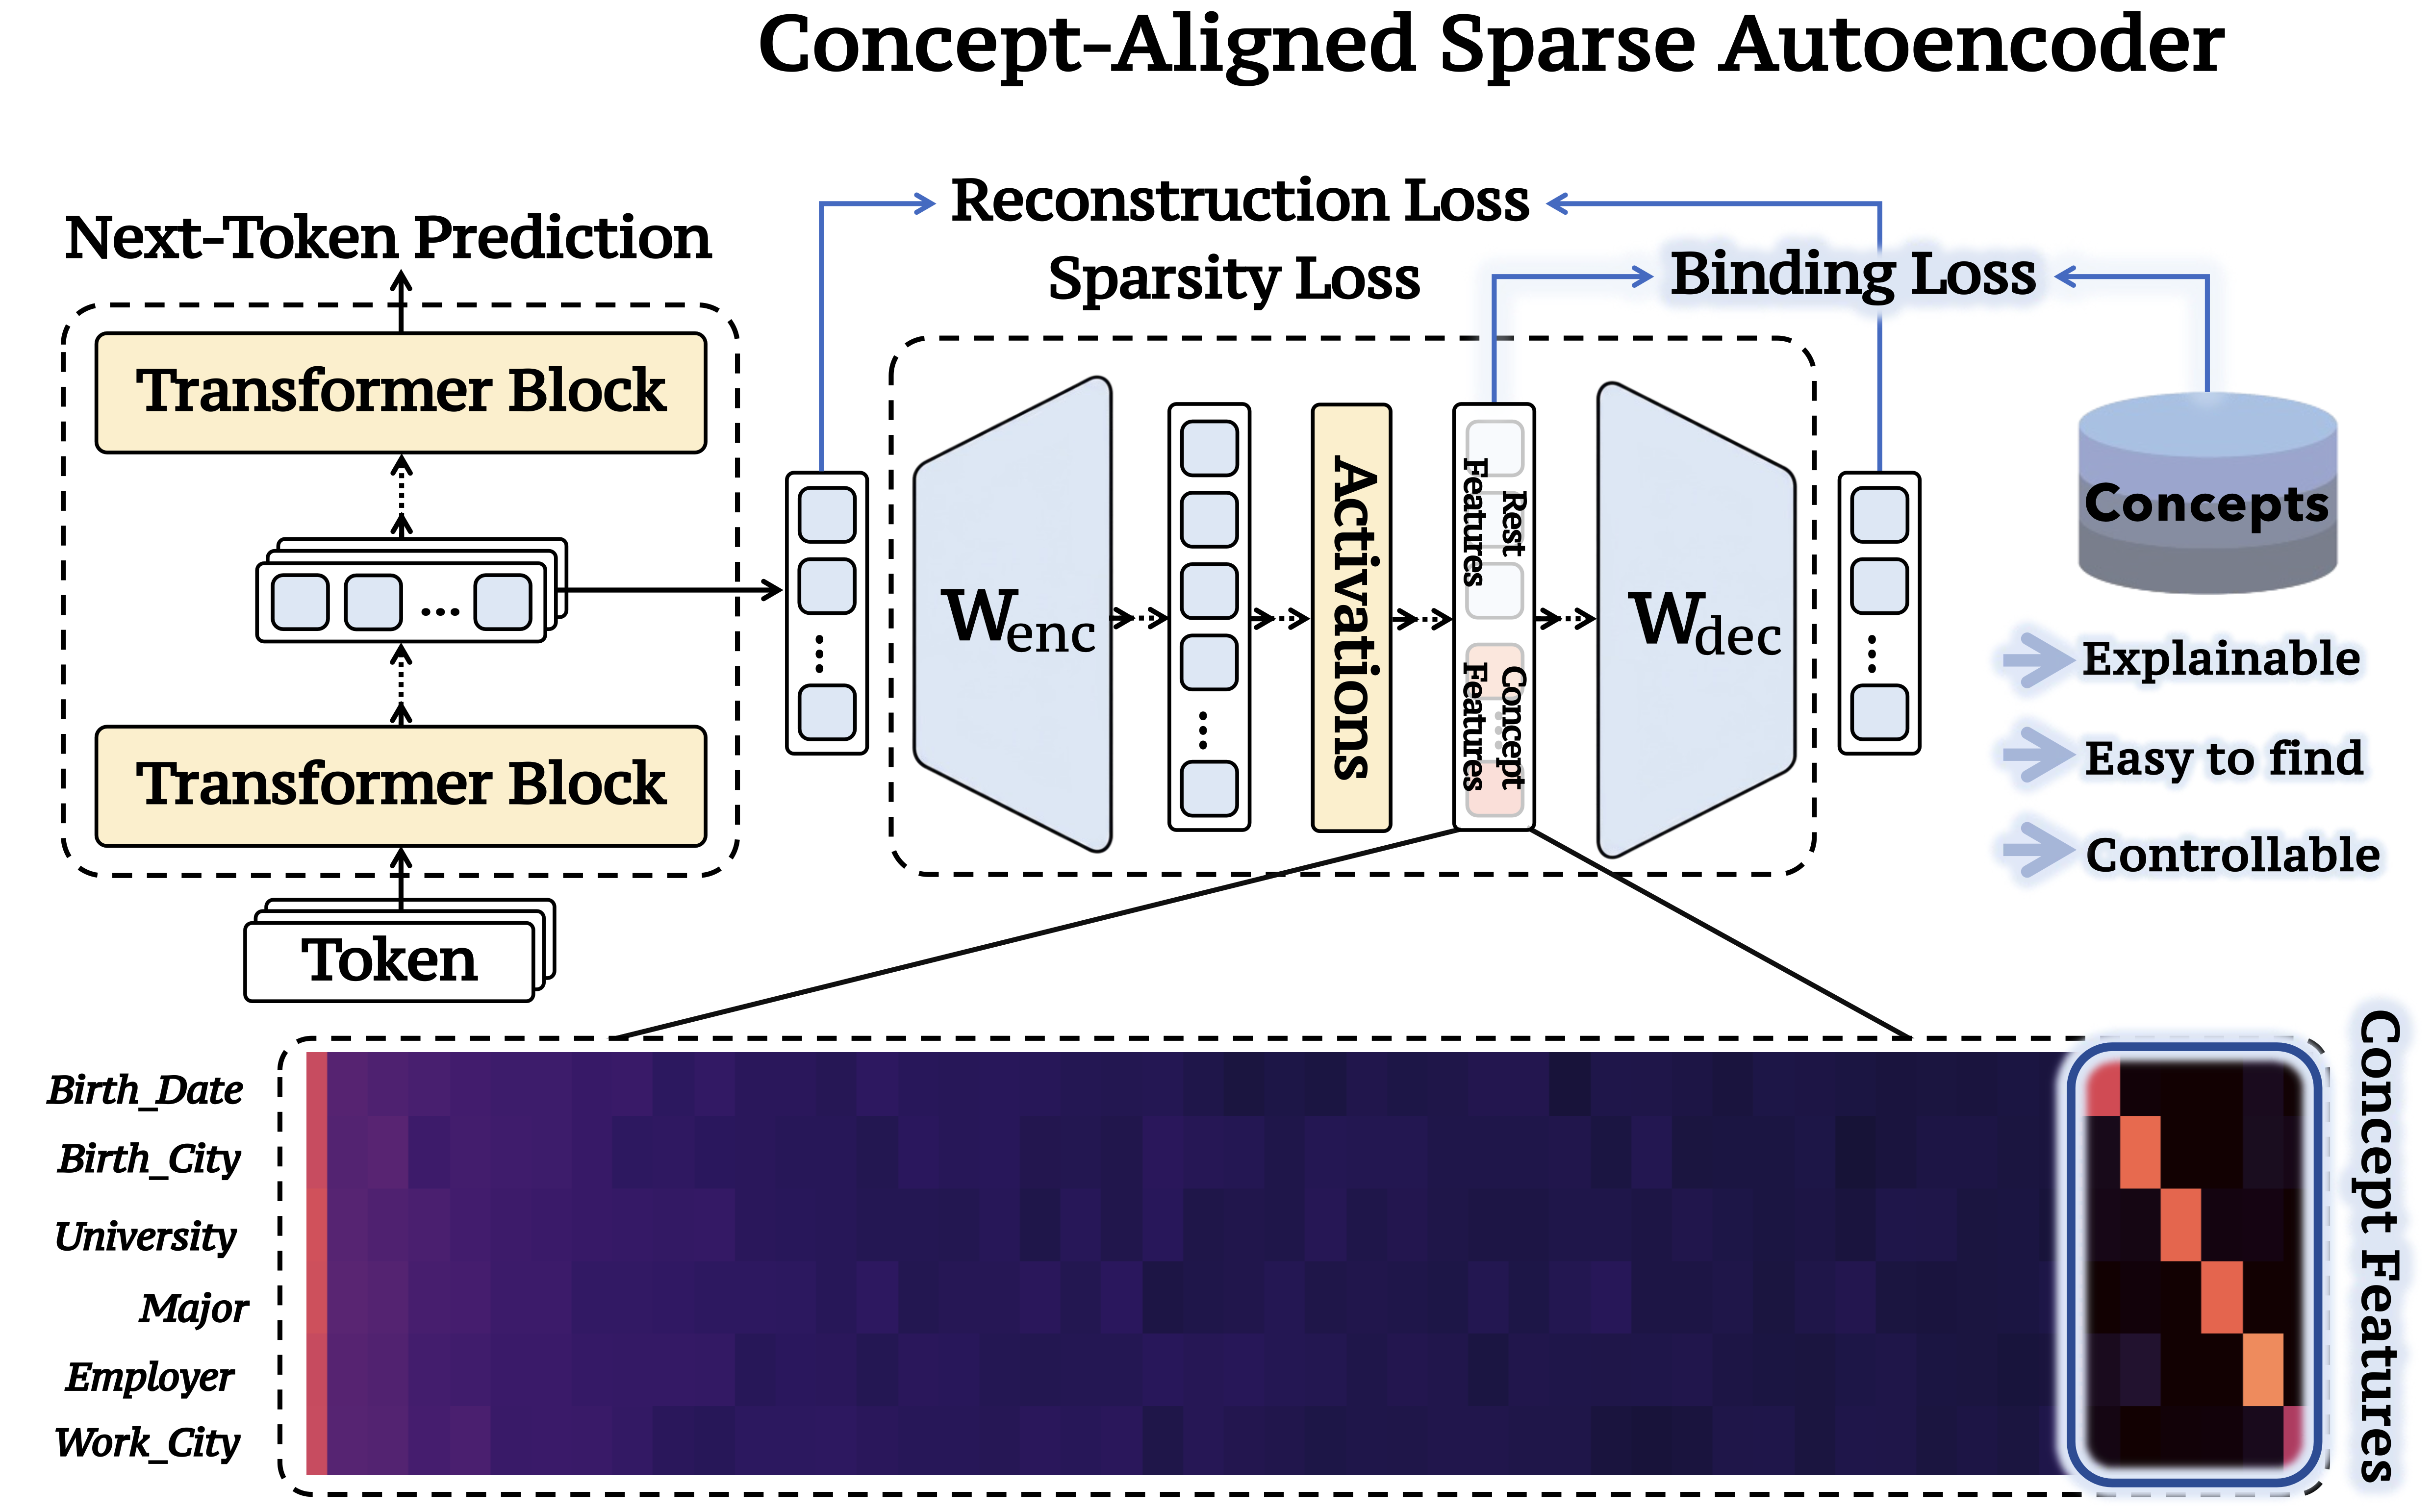
| Jul 03, 2026 | AlignSAE was accepted to TMLR 🎉 — the action editor recommended “Accept as is”. Grateful to all my co-authors! |
| Jun 15, 2026 | I officially joined Scale AI as an L4 Machine Learning Research Scientist on the Agents team, working on agents and RL environments! 🎉 |
| May 01, 2026 | EchoRL was accepted to ICML 2026 🎉 — reviving advantage-degenerated prompts in RLVR via rollout echoing. Congrats to all my co-authors! |
| Jan 05, 2026 | New chapter: I joined Abaka AI as a Senior Member of Technical Staff! 🚀 |
| Dec 19, 2025 | I graduated from the University of Arizona with a B.S. in Computer Science — summa cum laude (GPA: 4.0/4.0) in just over 2 years, and received the Best Senior Award 🎓 |
| Oct 19, 2025 | We took 2nd place at the Reddit Wildcat Hackathon 2025! |
| Oct 17, 2025 | Honored to earn UA’s Top 10 Undergraduate Research Travel Grant 🎓—headed to my EMNLP oral; see you in Suzhou. ✈️ |
| Aug 20, 2025 | Both of my submissions were accepted to EMNLP 2025 Main (Oral) 🎉 (Acceptance Rate: 22.16%). Grateful to all my co-authors, with special thanks to Profs. Liangming Pan, Mihai Surdeanu and William Wang. |